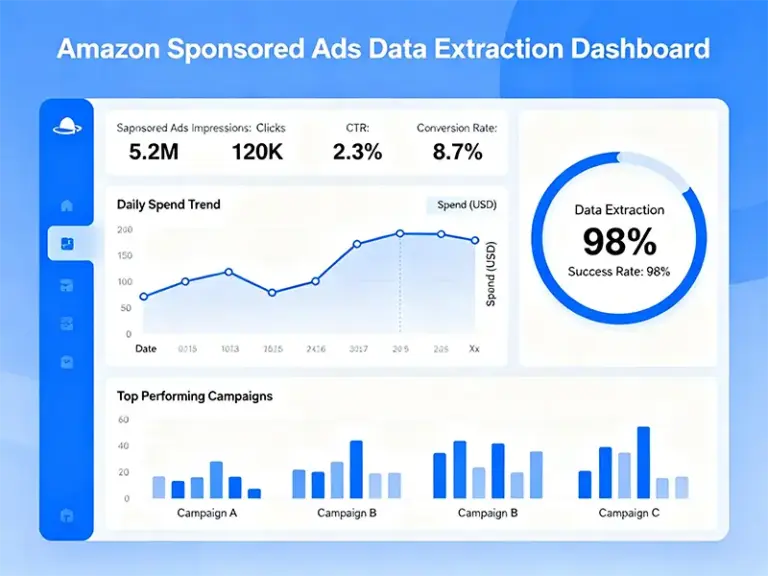

Scraper API is a professional web data extraction tool that can help you easily get the data you want from any website, without writing any code or installing any software. It supports various data sources, including web pages, images, videos, audio, PDF, JSON, XML, etc. It also provides rich data processing functions, such as data cleaning, format conversion, data storage, data analysis, data visualization, etc.
The main advantages of Scraper API are:
- It is a cloud service, you only need to send a simple HTTP request to use its functions, without worrying about servers, proxies, IP, verification codes, etc.
- It is a high-performance tool, it can handle thousands of requests at the same time, and return hundreds of data per second, ensuring the timeliness and accuracy of the data.
- It is a flexible tool, it can customize the data extraction plan according to your needs, and support various parameter settings, such as request headers, request methods, request body, timeout, retry, proxy type, etc.
- It is an easy-to-use tool, it provides detailed documentation and examples, teaching you how to use its API, and how to parse and process the returned data.
- It is an economical tool, it adopts a pay-as-you-go model, you only need to pay for the actual amount of requests you use, without prepayment or contracts.
The main features of Scraper API are:
- Web page extraction: It can extract the HTML content of any web page, supporting dynamic web pages, AJAX web pages, SPA web pages, etc.
- Image extraction: It can extract the images on any web page, supporting various image formats, such as JPG, PNG, GIF, SVG, etc.
- Video extraction: It can extract the videos on any web page, supporting various video formats, such as MP4, AVI, MOV, FLV, etc.
- Audio extraction: It can extract the audio on any web page, supporting various audio formats, such as MP3, WAV, OGG, AAC, etc.
- PDF extraction: It can extract the PDF files on any web page, supporting various PDF operations, such as merging, splitting, rotating, encrypting, decrypting, etc.
- JSON extraction: It can extract the JSON data on any web page, supporting various JSON operations, such as validation, formatting, compression, decompression, etc.
- XML extraction: It can extract the XML data on any web page, supporting various XML operations, such as validation, formatting, conversion, parsing, etc.
Now, you have learned the basic concepts, advantages and features of Scraper API, it’s time to start using it to collect Amazon data. Below, I will use “How to use Scraper API to quickly collect Amazon data” as the title, and help you write a SEO-friendly article, I hope you will like it.
How to use Scraper API to quickly collect Amazon data
Amazon is the world’s largest e-commerce platform, it has billions of products and users, and generates massive amounts of data every day. If you want to get some valuable data from Amazon, such as product information, prices, reviews, sales, rankings, etc., you may encounter the following problems:
- Amazon’s web page structure is complex and difficult to parse.
- Amazon’s web page content changes dynamically and requires simulating browser behavior.
- Amazon’s web page number is huge and requires a lot of requests and time.
- Amazon’s web page has anti-crawling mechanisms and requires bypassing verification codes and IP restrictions.
These problems may make you feel headache, or even give up the idea of collecting Amazon data. But if you use Scraper API, you can easily solve these problems, quickly collect Amazon data, without writing any code or installing any software. Below, I will teach you how to use Scraper API to collect Amazon data, only need three steps:
- Step 1: Register a Scraper API account and get an API key.
- Step 2: Construct a Scraper API request and send it to the Scraper API server.
- Step 3: Receive the data returned by Scraper API and process and analyze it.
Step 1: Register a Scraper API account and get an API key
To use Scraper API, you first need to register a Scraper API account and get an API key, which is your credential to call Scraper API. Registering a Scraper API account is very simple, you just need to visit [Scraper API official website], click the “Register” button in the upper right corner, fill in your email and password, and you can complete the registration. After registration, you will receive an email containing your API key, you can also view your API key on your account page. Your API key is a string of letters and numbers, similar to this:
sk_1234567890abcdef1234567890abcdef
You need to keep your API key properly, do not leak it to others, otherwise your account may be abused or stolen. You can modify or reset your API key on your account page at any time, if you think your API key has been leaked or insecure, you can immediately change to a new API key.
Step 2: Construct a Scraper API request and send it to the Scraper API server
With the API key, you can start to construct a Scraper API request. Scraper API request is a standard HTTP request, which consists of the following parts:
- Request method: Specify the operation you want to perform on the target web page, such as GET, POST, PUT, DELETE, etc. The default is GET.
- Request URL: Specify the address of the target web page you want to collect, such as https://www.amazon.com/.
- Request parameters: Specify the settings you want to make for Scraper API or the target web page, such as request headers, request body, timeout, retry, proxy type, etc. The parameters are attached to the request URL in the form of key-value pairs, separated by a question mark (?), and multiple parameters are connected by an ampersand (&). For example, if you want to set the request header to User-Agent: Mozilla/5.0, the request body to q=iphone, the timeout to 10 seconds, the retry to 3 times, and the proxy type to residential, you can construct the request parameters like this:
?headers={"User-Agent":"Mozilla/5.0"}&body={"q":"iphone"}&timeout=10&retry=3&proxy=residential
- Request key: Specify your API key, which is used to verify your identity and billing. The parameter name is api_key, and the parameter value is your API key. For example, if your API key is sk_1234567890abcdef1234567890abcdef, you can construct the request key like this:
?api_key=sk_1234567890abcdef1234567890abcdef
By splicing the above four parts together, you get a complete Scraper API request, similar to this:
https://api.scrapeapi.com/?api_key=sk_1234567890abcdef1234567890abcdef&url=https://www.amazon.com/&headers={"User-Agent":"Mozilla/5.0"}&body={"q":"iphone"}&timeout=10&retry=3&proxy=residential
You can use any tool or language that supports HTTP requests to send Scraper API requests, such as browsers, Postman, curl, Python, Java, etc. For example, if you use a browser, you can directly copy the Scraper API request to the address bar, and then press the enter key to send the request. If you use Python, you can use the requests library to send the request, as shown below:
import requests

api_key = "sk_1234567890abcdef1234567890abcdef"
url = "https://www.amazon.com/"
headers = {"User-Agent":"Mozilla/5.0"}
body = {"q":"iphone"}
timeout = 10
retry = 3
proxy = "residential"

params = {
    "api_key": api_key,
    "url": url,
    "headers": headers,
    "body": body,
    "timeout": timeout,
    "retry": retry,
    "proxy": proxy
}

response = requests.get("https://api.scrapeapi.com/", params=params)
Step 3: Receive the data returned by Scraper API and process and analyze it
After sending the Scraper API request, you can wait for the response from the Scraper API server. The Scraper API server will access the target web page and collect the data according to your request parameters, and then return a JSON-formatted response to you, containing the following fields:
- status_code: Indicates the status of the Scraper API request, such as 200 for success, 400 for parameter error, 500 for server error, etc.
- content_type: Indicates the content type of the target web page, such as text/html for web pages, image/jpeg for images, application/json for JSON data, etc.
- content: Indicates the content of the target web page, depending on
the content type, it may be a string, a byte stream, a JSON object, etc.
- error: Indicates the error information of the Scraper API request, if there is no error, this field is empty.
For example, if you send the above Scraper API request, you may receive a response similar to this:
{
    "status_code": 200,
    "content_type": "text/html",
    "content": "<!doctype html>\n<html lang=\"en-us\">\n<head>\n<meta charset=\"utf-8\">\n<title>Amazon.com: iphone</title>\n...\n</head>\n<body>\n<div id=\"a-page\">\n...\n</div>\n</body>\n</html>",
    "error": ""
}
You can use any tool or language that supports JSON parsing to receive and process the data returned by Scraper API, such as browsers, Postman, curl, Python, Java, etc. For example, if you use Python, you can use the requests library and the json library to receive and process the data, as shown below:
import requests
import json

# Send the request, omit the code

# Receive the response
response = requests.get("https://api.scrapeapi.com/", params=params)

# Parse the response
data = response.json()

# Get the status code
status_code = data["status_code"]

# Check if the status code is 200, indicating success
if status_code == 200:
    # Get the content type
    content_type = data["content_type"]
    # Get the content
    content = data["content"]
    # Process the content according to the content type
    if content_type == "text/html":
        # If it is a web page, you can use BeautifulSoup or other libraries to parse the HTML, and extract the data you want, such as product information, prices, reviews, sales, rankings, etc.
        pass
    elif content_type == "image/jpeg":
        # If it is an image, you can use Pillow or other libraries to process the image, such as saving, cropping, rotating, scaling, filtering, etc.
        pass
    elif content_type == "application/json":
        # If it is JSON data, you can directly use the json library to process the JSON, such as converting, validating, formatting, compressing, decompressing, etc.
        pass
    else:
        # If it is other types, you can process it according to your needs
        pass
else:
    # If the status code is not 200, indicating failure, you can get the error information
    error = data["error"]
    # Print the error information
    print(error)
This way, you have completed the process of using Scraper API to collect Amazon data, isn’t it easy? You can modify the parameters of the Scraper API request according to your needs, and collect different web pages and data, to achieve your data analysis and mining goals.
Summary
In this article, I introduced the basic concepts, advantages and features of Scraper API, and how to use Scraper API to collect Amazon data. I hope you can learn from this article that Scraper API is a professional web data extraction tool that can help you easily get the data you want from any website, without writing any code or installing any software. It supports various data sources, including web pages, images, videos, audio, PDF, JSON, XML, etc. It also provides rich data processing functions, such as data cleaning, format conversion, data storage, data analysis, data visualization, etc. Its main advantages are cloud service, high performance, flexibility, ease of use and economy.
If you are interested in Scraper API, you can visit [Scraper API official website], register a free account, get an API key, and start your data collection journey. You can also check [Scraper API documentation], to learn more about the Scraper API request parameters and response fields, as well as some useful Scraper API examples. If you have any questions or suggestions, you can contact [Scraper API customer service], they will be happy to help you and answer you.
Thank you for reading this article, I hope you like it, and I hope you can use Scraper API to collect Amazon data, and achieve your data analysis and mining goals. Good luck!